Coverage
- Sampled QA
- One or two percent, pulled by hand
- Kilevel
- Every conversation, with no sampling plan
Not out of negligence — more was never feasible. A person listening to a call and filling in a form manages a handful a day. So the question in this sector is not whether an AI can hold conversations; it is how much of what already happens anybody can see at all.
One or two percent of conversations, chosen by somebody with an opinion, scored on a form, days later. A breach in the other ninety-eight percent does not exist, because nobody listened to it.
Every conversation read against the same pack, human and AI, on one scale — and every finding carries the sentence it came from. What stands out is not who got reported, it is what fell below the line.
The difference between a number a compliance officer acts on and one they argue about is exactly this: can you see in thirty seconds where it came from. Any field can carry the part of the conversation it was inferred from, stored next to the value rather than reconstructed when somebody asks.

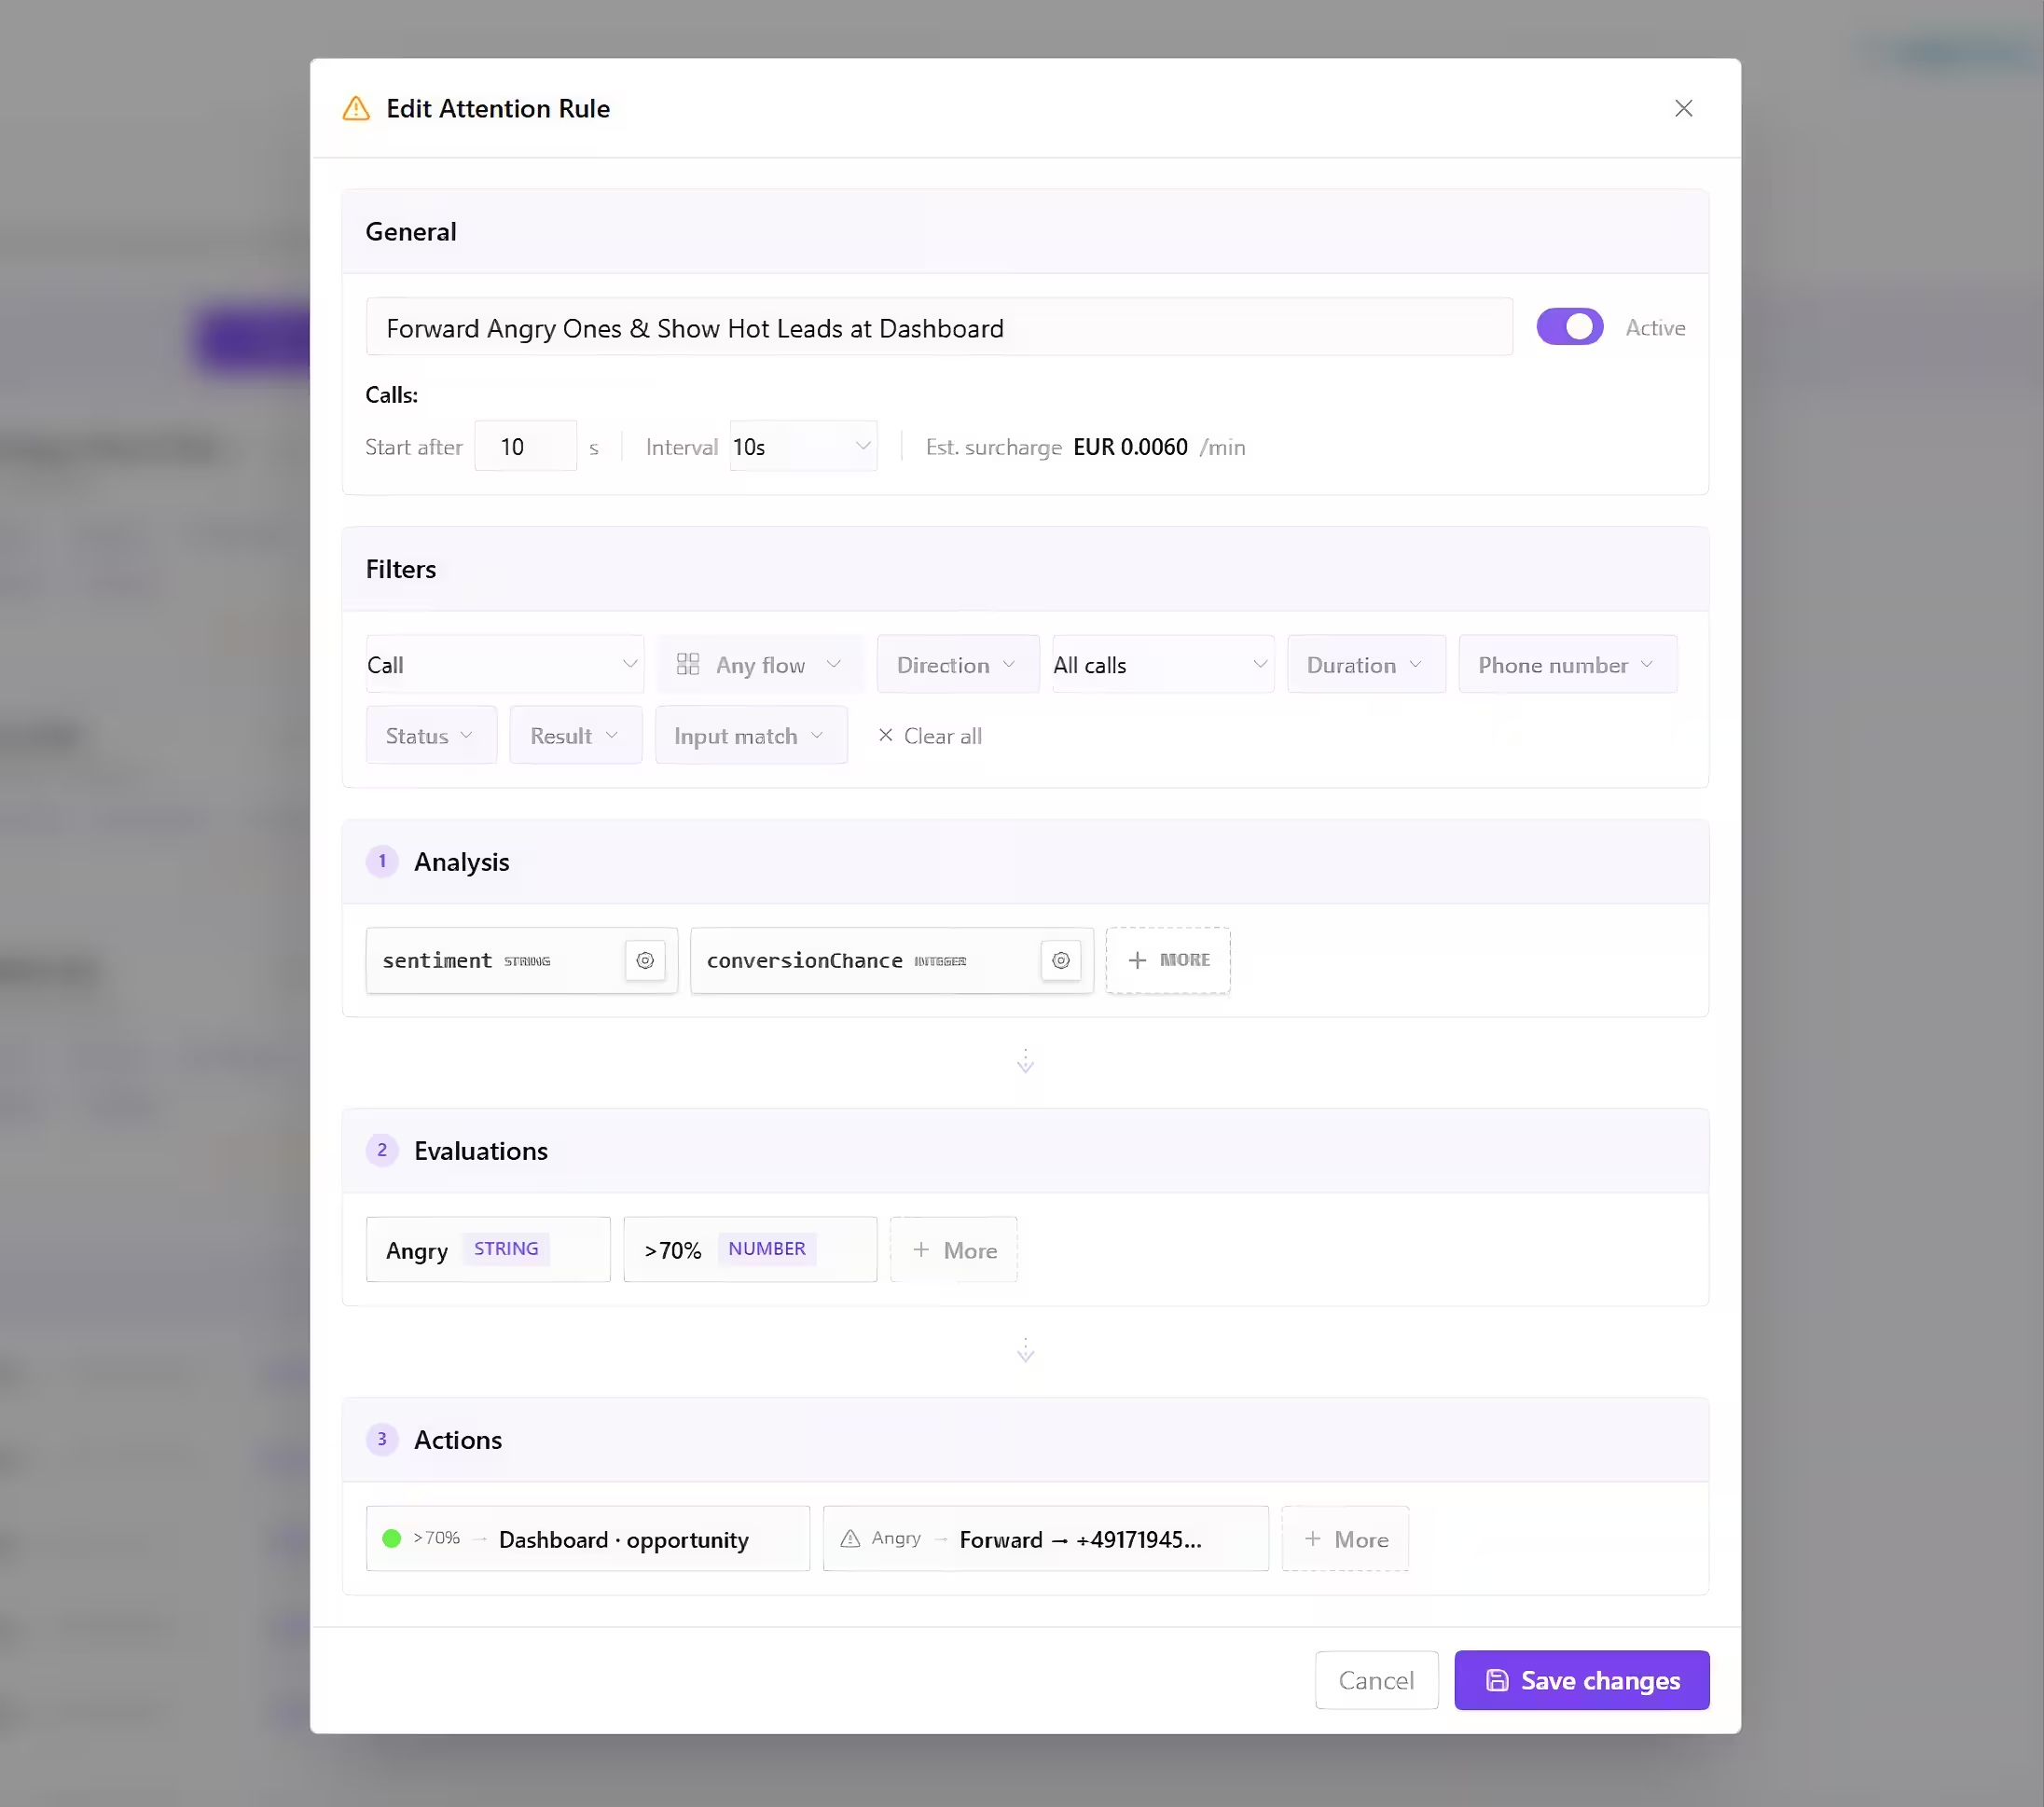
Suitability, risk warnings, costs disclosed, cooling-off explained — each a typed field able to carry the part of the conversation it was read from. A disputed finding is a thirty-second check rather than a re-listen.
Seven dimensions on which a sample and a complete read differ. The last one is the one most tenders forget to ask about.
| Compared against | Dimension | Sampled QA | Kilevel |
|---|---|---|---|
| Oversight of conversations | Coverage | One or two percent, pulled by hand | Every conversation, with no sampling plan |
| Selection | Whoever stands out, or whoever was reported | All of them — what stands out is what falls below the line | |
| Evidence | A note on a QA form | The field, and the sentence it was read from | |
| Timing | Days to weeks after the conversation | During it, when a rule reads the field | |
| Human and AI | Two processes, two yardsticks | One pack, one scale, one table | |
| Breaches | Disappear into an average | Fields of their own, where TRUE is the failure | |
| Existing recordings | Only what ran on this platform | Recordings from the phone system you already have |
Writing good metrics is a specialist job, and a firm that invents its own can never compare itself to anything. These two are fixed for that reason — your own fields sit alongside them, not instead of them.
Built around the question a regulator actually asks: was suitability assessed, were the warnings given, were the costs disclosed — and was pressure applied or a return implied. Several items are deliberately worded so that TRUE is the bad outcome, so a breach can never come out as a high score.
Built around what regulators and auditors check: identity before any disclosure, no third-party leakage, mandatory notices, hardship and pressure. The most important part of it is not a score but a stop — when somebody says they cannot pay because of illness or job loss, the script ends.
A live rule on the running conversation. Once the call has ended the decision is worth nothing.
Both packs, the scorecards, the KPI boards and the standing rules are set out in full under Performance Analytics. The calling machinery — windows, ceilings, retries — is under Outbound.
Not the advice. The thousands of short, identical, entirely necessary conversations around it — payment reminders before arrears, periodic reviews, address confirmations, card verifications — and the hand-off to a person the moment one of them has to stop.
None of these is an advice conversation. Together they are most of a firm's call volume.
Describe the product and the conduct rules around it, and the AI assistance drafts the agent, the schema with each field's direction declared, the live rule against a field that exists, and the campaign workflows around them. It comes back as an explicit list of individual edits with its assumptions stated — and nothing touches a live campaign until you have said so. In a regulated conversation that review step is the control, not a nicety.
Kilevel provides technical infrastructure. It does not give financial advice, carry on any regulated activity, or certify compliance. Whether an AI agent may hold particular conversations in your jurisdiction, which notices are mandatory, when recording is lawful, and how long evidence must be retained are matters of the supervisory regime that applies to you; responsibility for those rests with the operator.
Every conversation, human and AI, on one scale
A review becomes reading rather than re-listening
Read on the running call, with a forward on it
Pressure and implied returns get fields of their own
Join Europe's largest infrastructure enterprises already running their call operations on Kilevel with premium AI quality.
Everything you need to know about Kilevel.
Kilevel is a full-stack AI operations platform for businesses that communicate at scale. It unifies phone calls, WhatsApp, SMS, email, and web conversations under a single AI-native operating system, with visual workflow automation, omnichannel inbox, AI conversation analysis, and real-time operational control. From solo operators to enterprise teams, Kilevel runs autonomously across your entire communication stack.
Legacy IVRs follow rigid scripts. Chatbots handle text in isolation. Kilevel is an AI-native operations platform that handles real phone calls, WhatsApp, SMS, email, and web conversations simultaneously, with genuine contextual understanding. Agents adapt mid-conversation, book appointments, trigger follow-up automations, analyze every interaction, and hand off to humans when appropriate. The entire stack runs from a single platform: inbound queue, outbound campaigns, post-call intelligence, and operational reporting.
Yes. You can build and test your AI agent for free using our library of ready-made industry templates or by starting from scratch. Design call flows, configure channels, and connect integrations before going live. When you deploy, you pay a monthly subscription fee, which already includes a bundle of free AI minutes per month. Any usage beyond the included allowance is billed on a pay-as-you-go basis. No seats, no surprise fees.
No seats, no per-user charges. Kilevel combines a monthly subscription with usage-based pricing: each plan includes a pool of free AI minutes per month, and additional usage beyond that is billed at a per-minute rate. Building, testing, and configuring agents is free. Once live, costs scale predictably with your volume. Enterprise customers with high-volume commitments can discuss custom pricing agreements.
Most teams ship their first agent within a day. Kilevel comes with a library of industry-specific templates that cover the most common call flows and channel configurations out of the box. Pick a template, configure your agent's persona and rules, connect your tools, and deploy, no code required. Custom flows are built visually, and the AI flow assistant can generate an entire flow structure from a single descriptive sentence.
Kilevel gives your team leverage, not a replacement. AI agents absorb the volume of after-hours calls, common questions, appointment bookings and multilingual conversations, so your staff can focus on complex cases that genuinely need a human. Built-in sentiment analysis and configurable handoff triggers mean the AI always knows when to step aside.
The platform, the database and your recordings run on Google Cloud in Frankfurt, Germany, and the telephony infrastructure sits in a German data centre. Speech and language providers are used through their EU endpoints wherever the provider offers one. Where a provider processes outside the EU, that transfer runs on Standard Contractual Clauses, and every such provider is named with its processing region in our public Trust Center. An Article 28 data processing agreement applies from day one, with no separate negotiation, and we never use your data to train models.
Yes. Agents can detect a caller's language and respond accordingly, or you can configure language-specific flows per channel. This is particularly relevant for European businesses serving customers in German, French, Spanish, Dutch, and other languages alongside English, all within the same platform, without duplicating your entire agent setup.
No. The platform is designed for operators first. Flow building, agent configuration, channel setup, and integration connections are all no-code. Developers who want deeper control get a full REST API, webhooks, MCP-compatible tool discovery, and prompt-level customization, but none of it is required to run a production deployment. Non-technical teams operate Kilevel every day.
Completely. Every flow, agent behavior, escalation rule, and analysis signal is configurable, visually, without code. You define the tone, language, fallback responses, and handoff conditions. Advanced users can go further with prompt modules, templating parameters, flow templates, and a full REST API. If your workflow is unusual, Kilevel almost certainly supports it.
Complete control. You define tone, language, permitted topics, and response templates using prompt modules and templating parameters, reusable building blocks your agents draw from consistently. Escalation rules trigger human handoff based on sentiment, topic, or conversation outcome. Every configuration is fully testable in a sandbox before it touches a real customer.
You have full control over what your agent says. Define tone, language, and exact response templates. Escalation rules let you specify when a conversation gets transferred to a human, based on topic, negative sentiment, or repeated failed attempts. Everything is testable before it goes live, and you can iterate on agent behavior at any time.
Yes, and often without any setup at all. Kilevel supports MCP (Model Context Protocol), which means it can automatically discover and digest integrations from modern CRMs, ERPs, and data platforms. For everything else, there are webhooks, a REST API, and pre-built connectors. Your data flows in and out on your terms.
Both directions are fully supported. Kilevel uses MCP (Model Context Protocol) to automatically discover and integrate modern CRM and ERP systems, often with zero connector setup. In the other direction, Kilevel's REST API lets your own tech stack trigger calls, campaigns, and automations externally, and pull conversation results, analysis, and outcomes back into your systems on demand.
Yes, automatically. Kilevel scales concurrent lines dynamically, whether you're handling 10 conversations or 10,000, the infrastructure adjusts without manual intervention. The Operations Control Center gives you live visibility into concurrency, queue depth, and agent performance, so you're never operating blind at scale.
Your data sits in Frankfurt, Germany: platform, database and recordings on Google Cloud, telephony in a German data centre. Credentials are encrypted at the column level with AES-256-GCM, every query is scoped to its owning account, sub-users carry project-specific roles, and administrative actions are written to a reviewable audit trail. We process only on your documented instructions and never train models on your data. The full subprocessor list, with the processing region of each, is published in our Trust Center.
Kilevel agents are designed to manage uncertainty without frustrating the caller. They can ask clarifying questions, offer alternate paths, or escalate to a live operator, automatically, based on rules you set. The Attention Suite enables immediate human takeover mid-conversation without any disruption to the customer experience.
Kilevel agents handle uncertainty without derailing the experience. They can ask clarifying questions, reroute the conversation along alternate paths, or escalate to a live operator, all automatically, based on configurable rules. The Attention Suite lets operators intervene instantly mid-call, taking over the conversation without the customer noticing any disruption.